Comparing fraud taxonomies and how to use them
An overview of emerging fraud taxonomy frameworks and how they compare to established cybersecurity standards. This post examines the Fed's FraudClassifier and ScamClassifier, Stripe's FT3 framework, and FS-ISAC's coordination model, explaining what each solves, how they complement each other, and why no single taxonomy is enough. Learn how leading organizations are combining these frameworks to break down silos and operationalize fraud intelligence more effectively.
 Arjun Bisen, CEO and cofounder
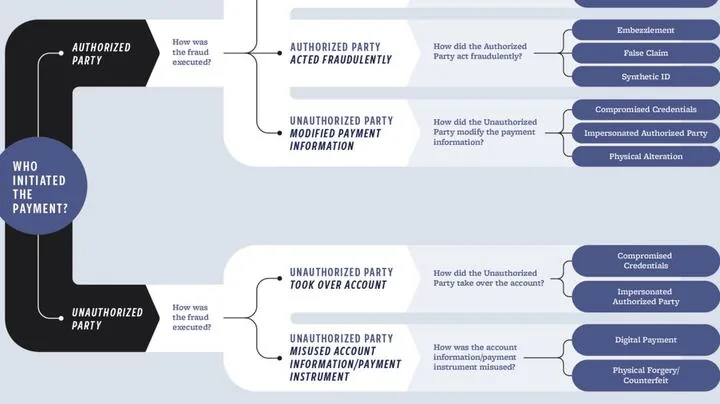
I've been in many conversations with cyber, intel, and fraud experts where they've praised taxonomies like the MITRE ATT&CK framework and sharing of Indicators of Compromise (IOCs) that are commonly understood in cyber intelligence and wished that the fraud taxonomy was as well developed. That would allow them to throw all the fraud accounts/IOCs into a centralized system to take automated action/scoring.
That said, there are some very useful fraud taxonomies that are being worked on by some of the best in the business, which could have a big impact on how we organize. Each of the major frameworks focuses on solving a different problem.
The Fed's FraudClassifier has become a foundational standard for banks and payment providers. Its strength is simplicity: a clear, payment-agnostic way to distinguish authorized vs. unauthorized fraud and report losses consistently across the industry.
The Fed's ScamClassifier builds on this by addressing a major blind spot, authorized scams. By breaking scams into concrete types (romance, investment, impersonation, etc.), it added much-needed clarity to an area that was previously vague, on the rise, and inconsistently labeled. The Fed has a useful guide on how to leverage this classifier.
The most tactical of all, the FT3 framework, built by Vincent Passaro and the good people at Stripe, takes a very different approach. Modeled after cybersecurity frameworks like MITRE ATT&CK, it classifies fraud by the tactics and techniques used by attackers. This is powerful for detection and threat intelligence, but also more complex to operationalize. However, as a technology company, we've found useful ways to leverage their GitHub repo to automate the classification of fraud materials, leveraging our AI agents. We're always happy to share our approach with anyone interested.
Finally, FS-ISAC's Cyber Fraud Prevention Framework focuses less on classification and more on coordination. By mapping fraud across stages, from reconnaissance to monetization, it helps break down silos between fraud, cyber, and AML teams. It's especially useful in organizing info sharing via FS-ISAC's platform.
The takeaway: there's no single "best" taxonomy. The strongest fraud programs combine:
- Fed models for standardization and reporting
- FT3 for understanding adversary behavior
- FS-ISAC's framework for cross-team action
How are you all using these taxonomies today? What did I miss?
I generally feel like the data we need to tackle fraud exists but often sits in silos, is unstructured, and could really benefit from tighter classification that would allow it to be operationalized in a simple way.
Fifteen years in global risk at Stripe, Google and Twitter, including leading Stripe's fraud intelligence and onboarding risk team.
Cyber Pulse, in your inbox.
What changed in the threat landscape, what risk teams should watch, and one operational takeaway. Written by Arjun and Zara.
Stop chasing alerts. Start working ahead of them.
Overwatch turns real-time understanding of the criminal underground into the investigations and risk decisions your fraud and security teams have to make every day.